Select Projects

Anomaly Detection

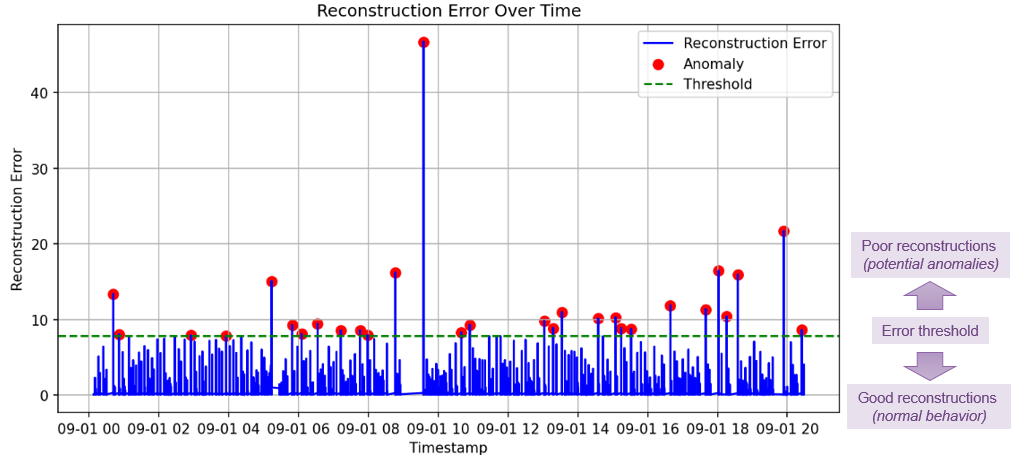
Capstone Project for Masters Program in partnership with Jefferson Labs. By leveraging historical sensor data, waveform signals, and system logs of the Spallation Neutron Source (SNS), created models to help detect potentially errant beams that would damage the system.

Visualization Techniques

Final Project for ODU CS625 - Data Visualization, collected data from publicly available sources for Medicare, Pharmacies and Department of Energy. The data was then cleaned and merged to analyze through visualizations created with VegaLite.

Behind the Analysis: My Skills

SQL

With over a decade of SQL experience, I’m comfortable creating and modifying tables, writing complex queries, and using CTEs to keep data tasks efficient and organized.

Python

4 years of experience using Python for data pre-processing and analysis, with a focus on cleaning, transforming, and analyzing datasets using libraries like pandas and NumPy.

Visualization

Experienced in creating impactful visualizations and dashboards using Tableau, Power BI, and the Microsoft Office suite. Skilled in turning complex data into clear, actionable insights for diverse audiences.

Statistical Analysis

Proficient at exploring data to identify patterns, trends, and insights that drive smarter decisions. Experienced in making sense of complex datasets in distribution and sales to reveal meaningful stories and support business goals.

Other Data Science Projects

Data Exploration & Visualization

Chronic Disease Prevalence & Related Hospitalization Modeling

This project was completed as part of my coursework in CS: 620: Intro to Data Science and Analytics. In this project, Python libraries were employed to investigate chronic illness trends along with a focus on prediction modeling to evaluate correlations between ashma rates and air qualty across the United States.
 The Google Colab notebook with all work done for the project can be found here.

Credit Card Retention

For this introductory course, data was explored using basic Python code to process and clean the dataset, create columns for feature engineering and finally to create visualizations.
 The Google Colab notebook with all work done for the project can be found here.


PySpark & Spark SQL

San Francisco Fire Department Respond Time

This project leveraged machine learning and other analytic methods to predict response times to incidents by the San Francisco Fire Department. To process the data, Spark SQL was utilized to pre-process the raw data that was then fed into a Random Forest model in PySpark.
 The Google Colab notebook with all work done for the project can be found here.


Natural Language Procecssing

The following code selections were done to meet requirements for CS 733: Natural Langauge Modeling
N-Grams

The code was developed to read through a list of financial new headlines, generate the n-grams, and then train various models to determine which model performed the best at generalizing unseen data.
 Repo with all work done for the project and how to utilize code can be found here.

Multi-class Sentiment Analysis

For this code, it was developed to read through a compilation of 1.6million tweets, from Kaggle dataset Sentiment140 dataset with 1.6 million tweets, create various language models and attempt to predict if the tweet had a positive or negative sentiment.
 Repo with all work done for the project and how to utilize code can be found here.

Transformer Encoder and Decoder

Built an encoder & decoder models using the Wikipedia Sentences & AG News datasets by tokenizing the sentences and preparing input–output pairs, trained the model using cross-entropy loss with teacher forcing to improve learning, and evaluated model using perplexity metric.
 Enocoder script located here, and Decoder script located here.